Which AI model is actually better?
Every model sits the same fixed Persian test: a 20-question report card and 8 interactive builds, from an arcade game and a santur to a Persian calendar and a 3D Azadi Tower. Code, a real browser and a jury from three companies give the score. Try every build yourself, right here.
01Current champion
02Leaderboard
Each model’s score is the mean of its runs (a model with one run so far is “provisional”) · cost = what the model itself charged for the whole test, jury not included| # | Model | Tier | MRMP score | Report card | Showcase | Mohsen’s take | Cost of answers | Speed |
|---|---|---|---|---|---|---|---|---|
| 01 | Anthropic: Claude Opus 5.5 anthropic/claude-opus-5.5 | S | 98.59 between 97.17 and 100 | 39 / 40 | 59.59 / 60 | – | $5.12 | 137 tok/s |
| 02 | OpenAI: GPT-6.1 Sol openai/gpt-6.1-sol | S | 94.42 between 92.71 and 96.13 | 38 / 40 | 56.42 / 60 | – | $1.01 | 59 tok/s |
| 03 | SpaceXAI: Grok 4.7 x-ai/grok-4.7 | S | 94.13Provisional | 36 / 40 | 58.13 / 60 | – | $3.40 | 134 tok/s |
| 04 | Google: Gemini 3.8 Flash google/gemini-3.8-flash | S | 93.03 between 92.83 and 93.23 | 36 / 40 | 57.03 / 60 | – | 74.8¢ | 179 tok/s |
| 05 | Google: Gemini 4 Argon google/gemini-4-argon | S | 90.85 between 89.23 and 92.46 | 33 / 40 | 57.85 / 60 | – | $1.33 | 85 tok/s |
| 06 | OpenAI: GPT-6 Luna openai/gpt-6-luna | S | 90.15 between 89.61 and 90.69 | 35 / 40 | 55.15 / 60 | – | 5.6¢ | 155 tok/s |
| 07 | MoonshotAI: Kimi K3 moonshotai/kimi-k3 | A | 83.06Provisional | 36 / 40 | 47.06 / 60 | – | $3.37 | 122 tok/s |
| 08 | DeepSeek V4 Pro 0813 deepseek/deepseek-v4-pro-0813 | B | 79.87Provisional | 28 / 40 | 51.87 / 60 | – | 16.8¢ | 176 tok/s |
| 09 | Qwen3.8 Max (0902) qwen/qwen3.8-max-0902 | B | 77.75Provisional | 36 / 40 | 41.75 / 60 | – | $3.03 | 54 tok/s |
| 10 | DeepSeek V4 Flash 0423 deepseek/deepseek-v4-flash | B | 68.78 between 62.02 and 76.4 | 26 / 40 | 42.78 / 60 | – | 2.3¢ | 112 tok/s |
| 11 | Anthropic: Claude Sonnet 5.5 anthropic/claude-sonnet-5.5 | C | 63.55Provisional | 34 / 40 | 29.55 / 60 | – | $4.02 | 202 tok/s |
| 12 | Z.ai: GLM 5.3 FlashX z-ai/glm-5.3-flashx | C | 62.9Provisional | 34 / 40 | 28.9 / 60 | – | 68.9¢ | 258 tok/s |
| 13 | Qwen3.8 Flash qwen/qwen3.8-flash | C | 54.34 between 52.96 and 55.71 | 29 / 40 | 25.34 / 60 | – | 31.6¢ | 72 tok/s |
Costs are in US dollars.
03Best build per challenge
The best build of each showcase challenge. Open a card to see every model’s build for that challenge.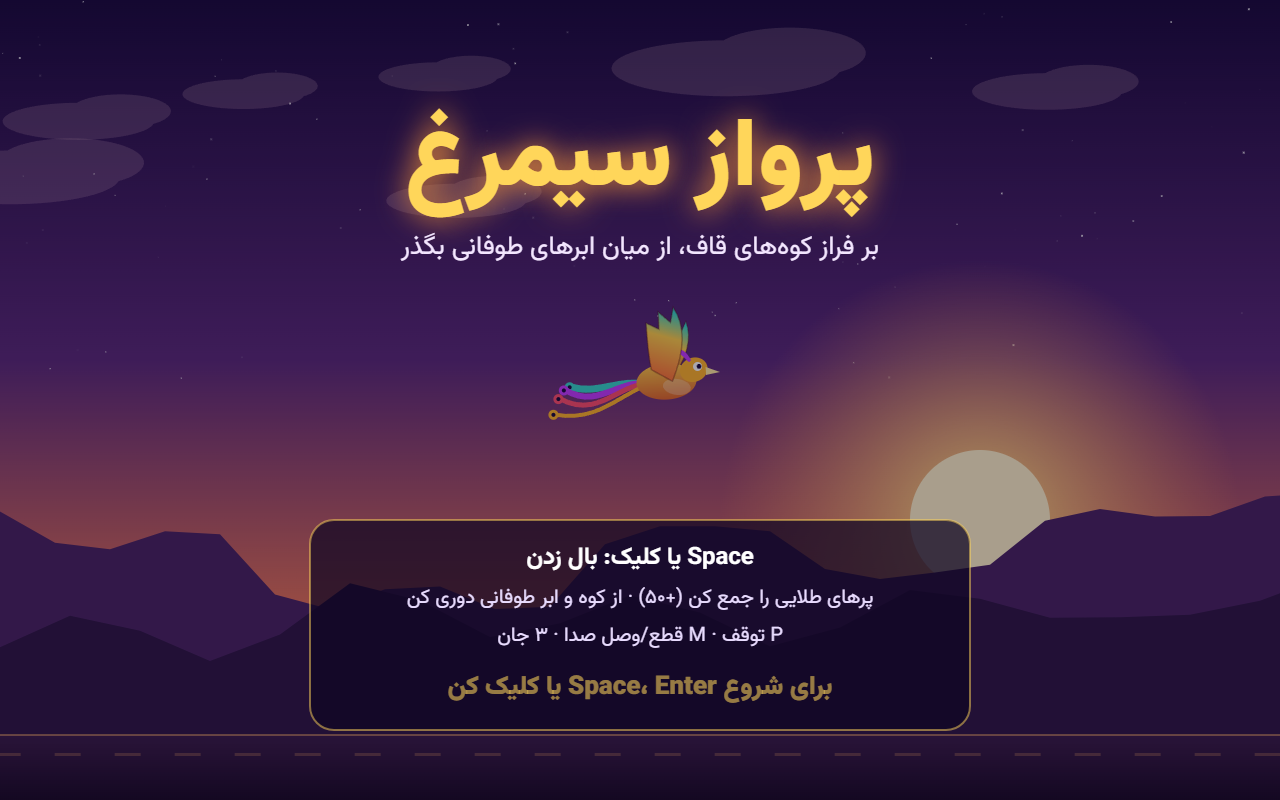 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
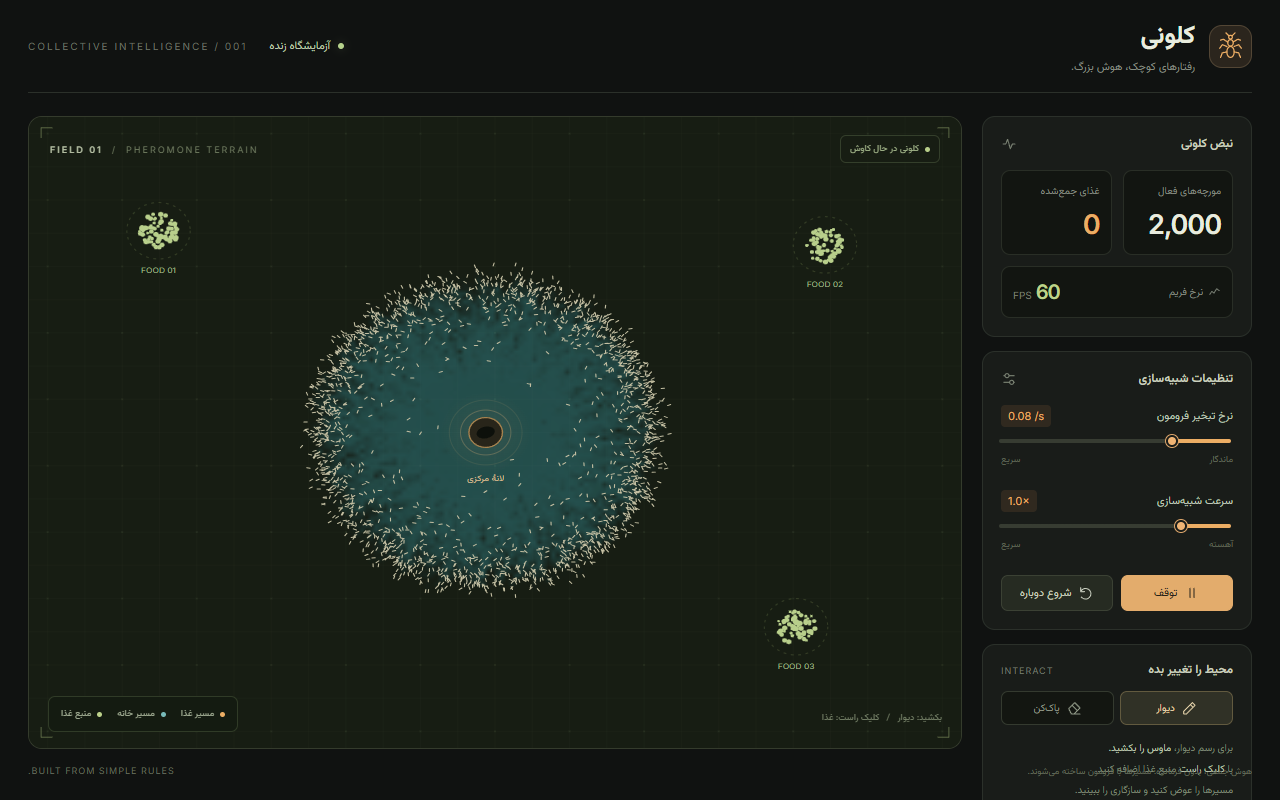 OpenAI: GPT-6.1 Sol · 7.5 of 7.5
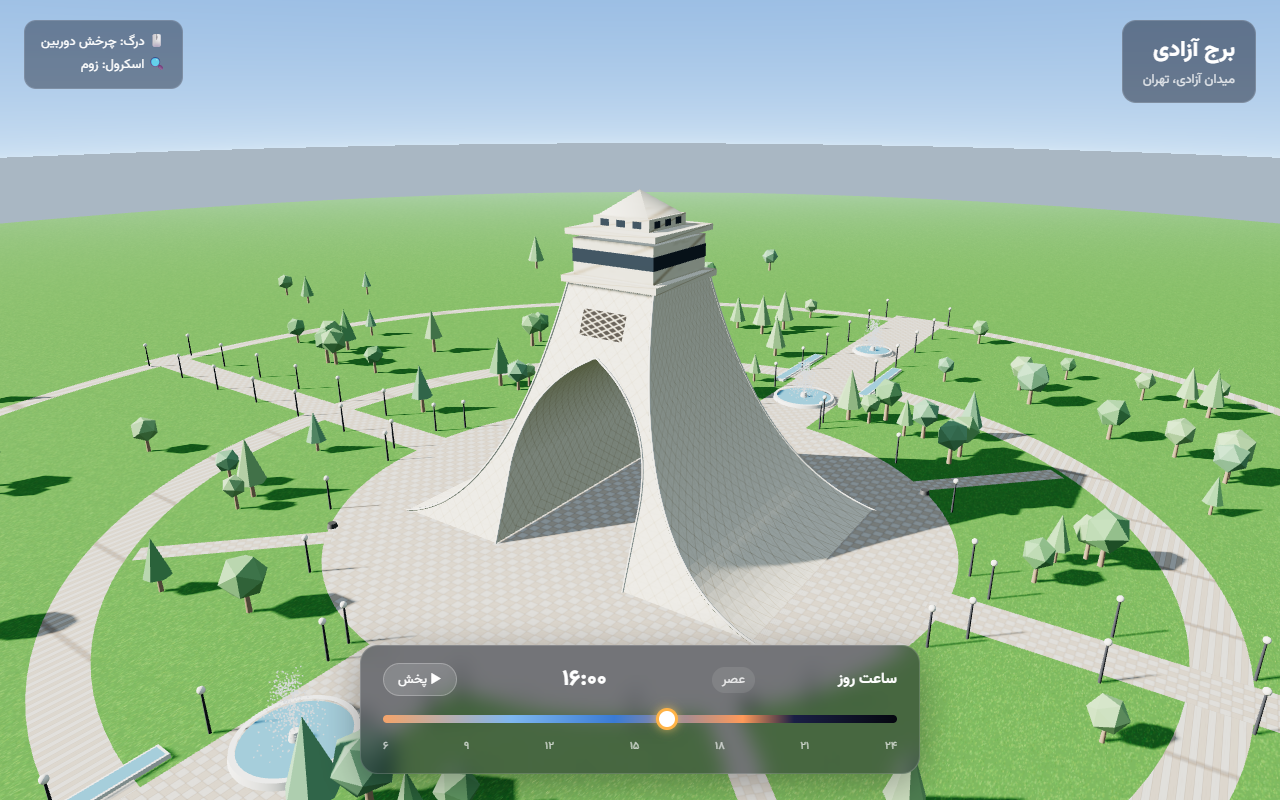 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
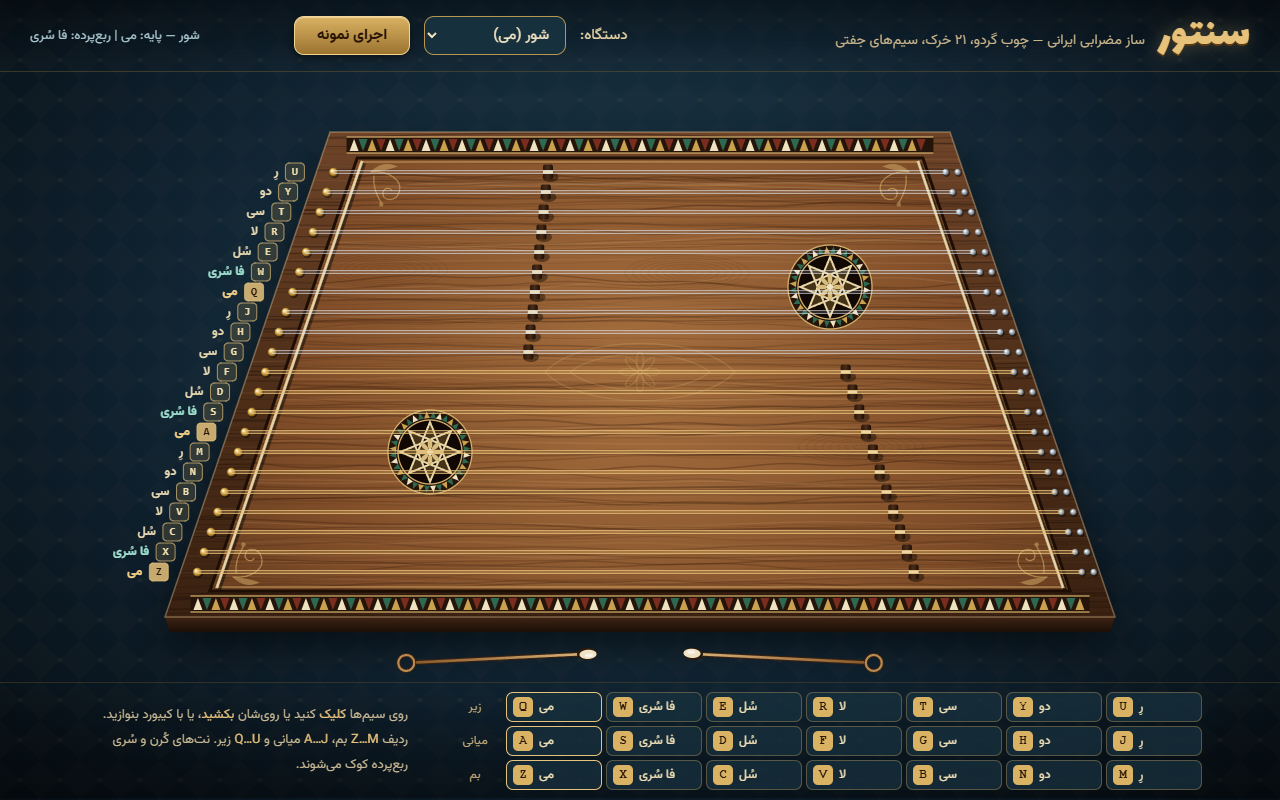 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
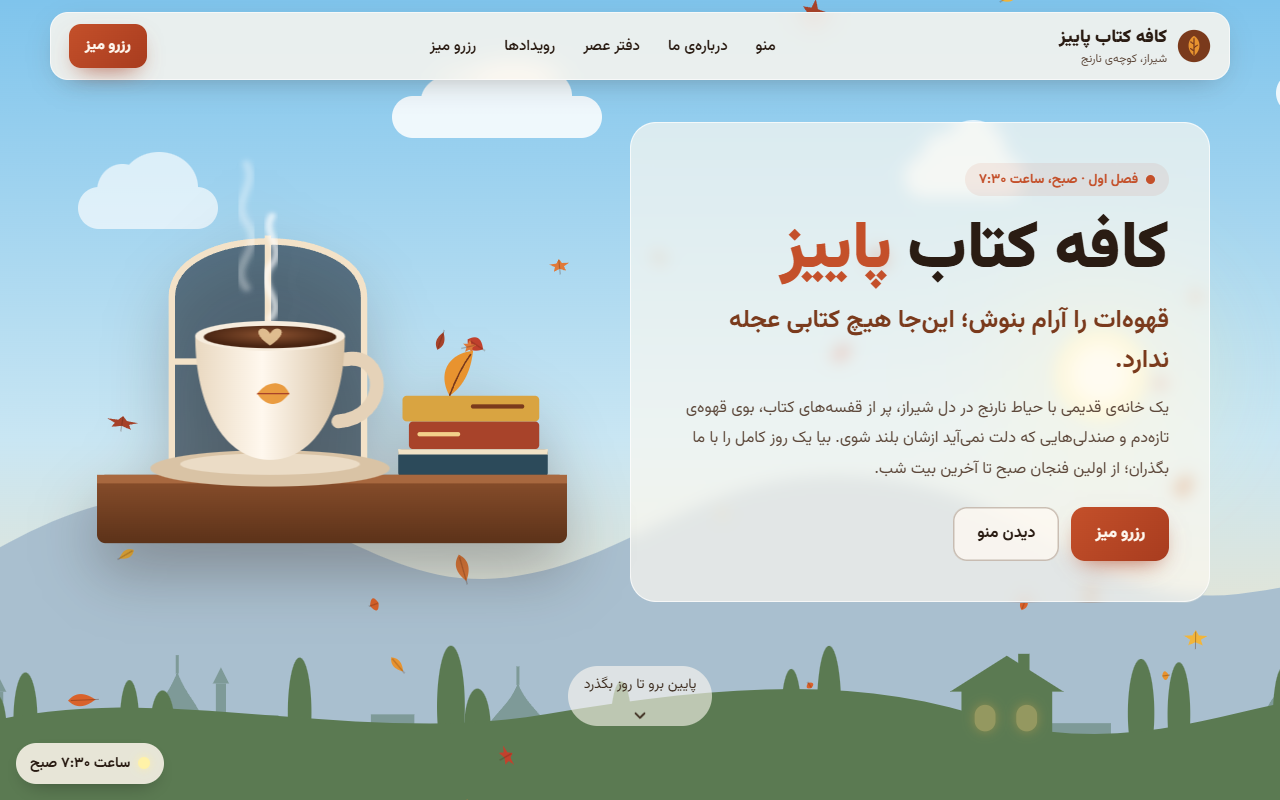 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
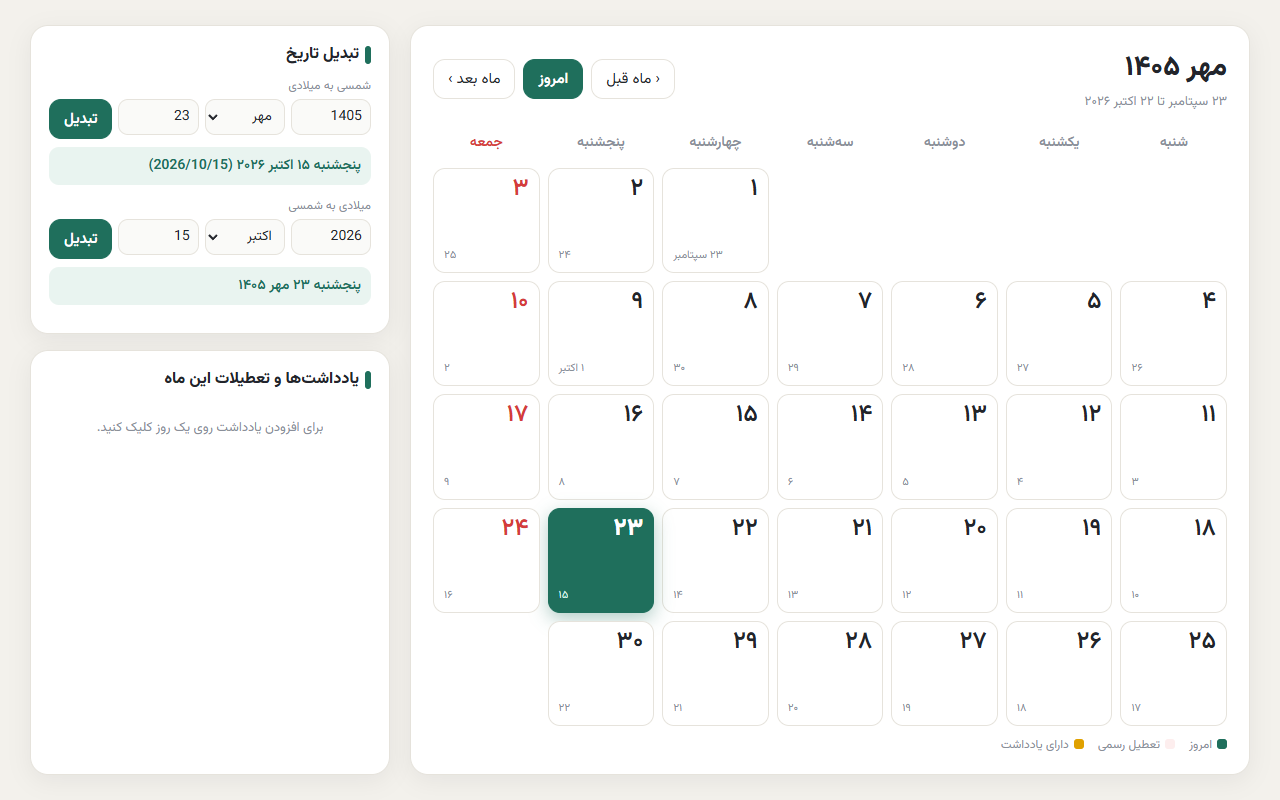 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
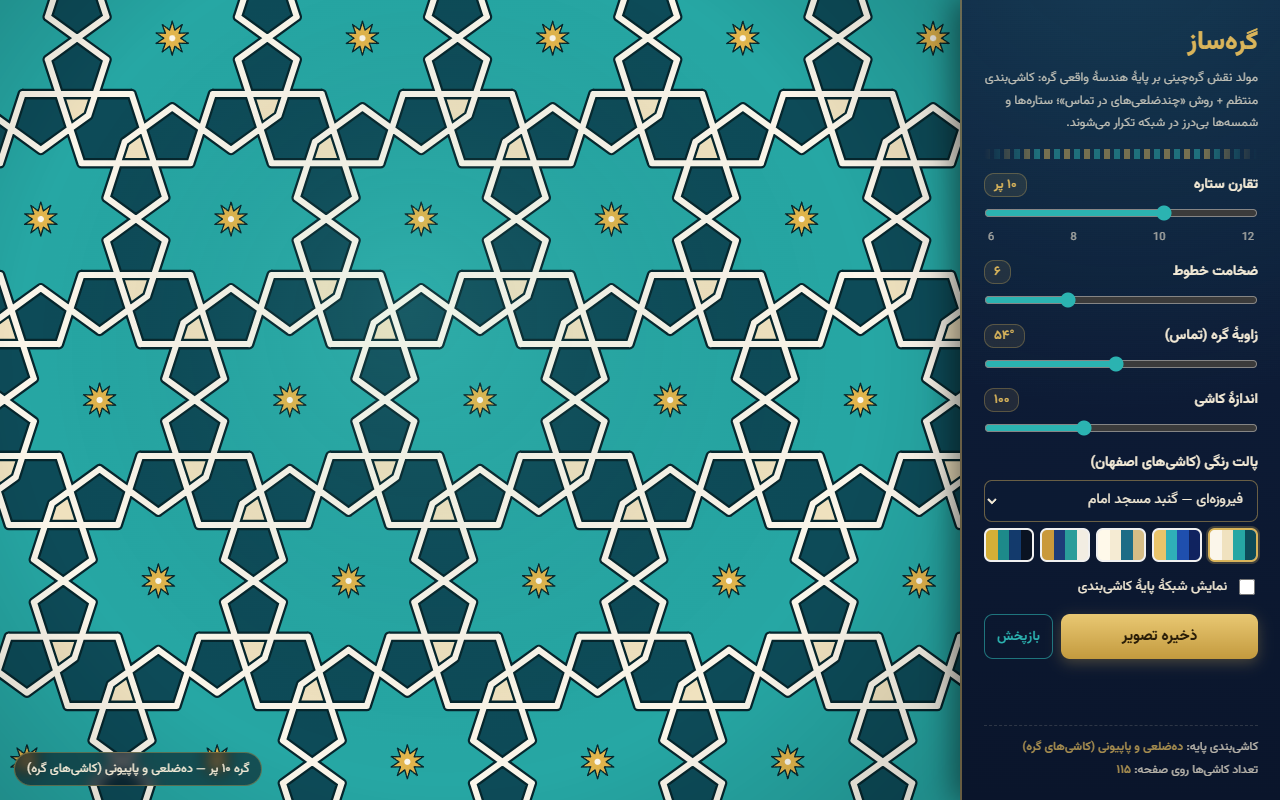 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
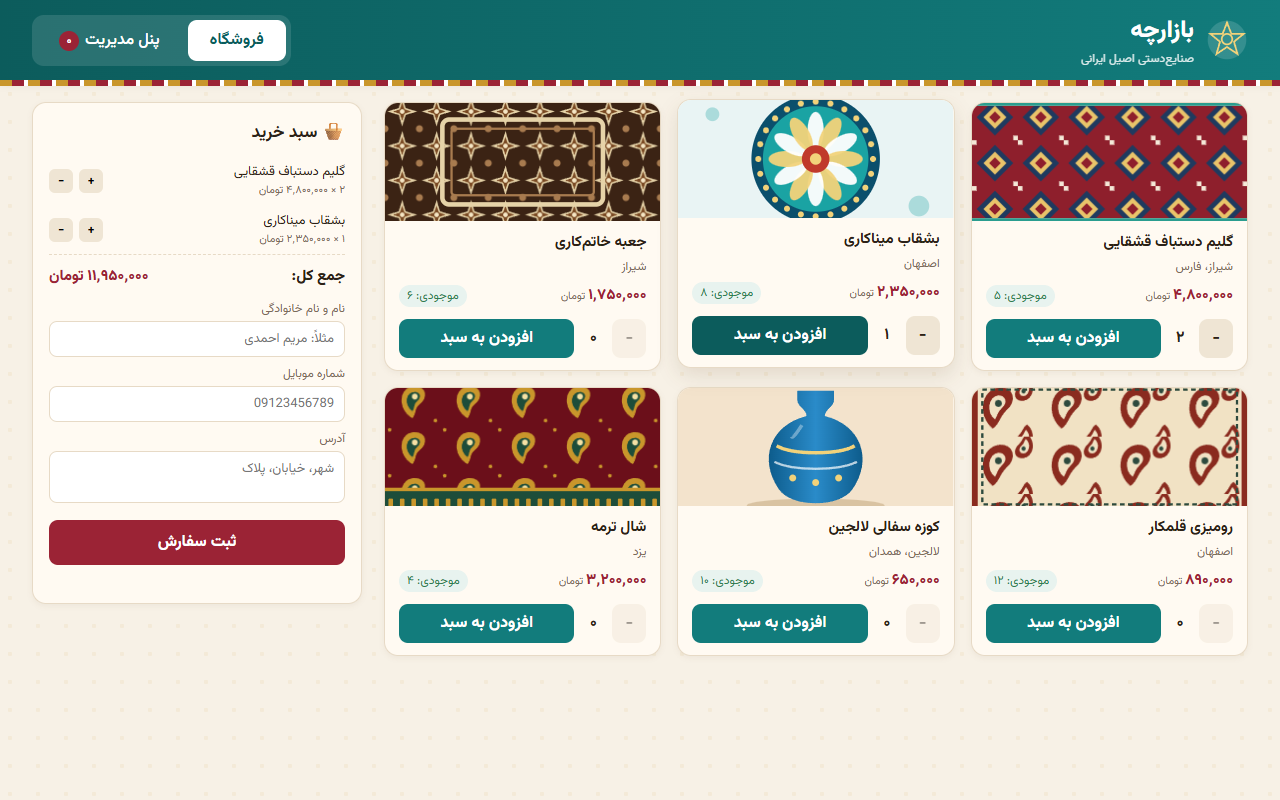 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
04Quality versus cost
Each dot is a model. Higher and further left (cheaper) is better value. Cost is what the model itself charged to answer the whole test, without the jury. The cost axis is logarithmic.
What is MRMP Bench?
MRMP Bench is a Persian benchmark for comparing AI models and large language models (LLMs). GPT, Claude, Gemini, DeepSeek, Grok, Qwen and the rest all sit the same fixed test in Persian: a 20-question report card and 8 interactive builds.
The score comes from code, an automated browser and a three-judge panel from three different companies, and every answer and build is published here. So you can see for yourself which model is best for work in Persian, what it costs and where it goes wrong.
Every new model, a new episode
I review each model’s results on camera on my YouTube channel: I run its builds, compare them with the champion and give my own verdict. The videos are in Persian.